|
Yanjiang Guo Hi! I am a final year PhD student in Computer Science at Tsinghua University, advised by Prof. Jianyu Chen. I received my bachelor's degree in EE also from Tsinghua University in 2022 . From March 2025 to Jan. 2026, I was fortunate to visit Stanford University and work with Prof. Chelsea Finn, founder of Physical Intelligence. My research focuses on building Physical AI that can learn and perform a wide range of tasks in the real world. I explore how pretrained foundation models can enable scalable learning and generalization, with a focus on vision-language-action policies and video-model-based policies. Currently, I also worked on agentic robot policies. Besides research, I enjoy watching and playing soccer⚽. I also love physics👾 — “Everything should be made as simple as possible, but not simpler.” Email / Scholar / Twitter / Github
Awards:
|
|
Selected Research (* indicates equal contribution)
|
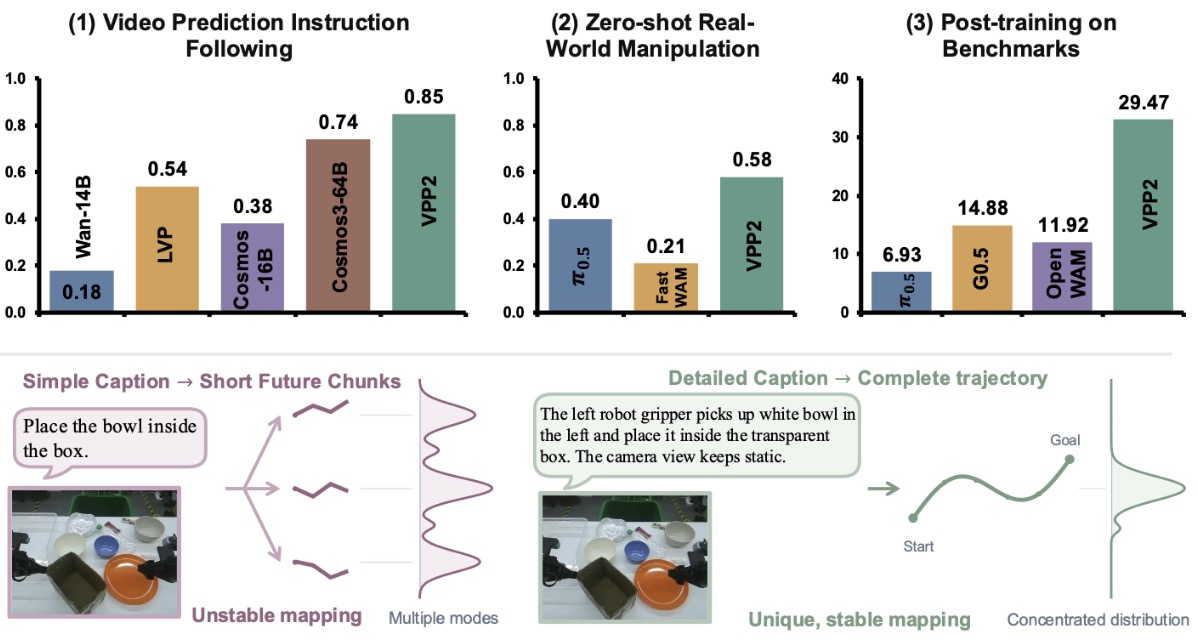
Video Prediction Policy 2: Predict Better, Act Better
Yanjiang Guo*, Haodong Yan*, Zhide Zhong*, Zhongru Zhang*, Qingyuan Yang*, Qingzhou Lu, Xiaoyu Chen, Yen-Jen Wang, Shuying Deng, Chenghan Yang, Puzhen Yuan, Chenxin Liu, Tun Ban, Xiang Zhu, Yichen Liu, Kun Feng, Haoang Li, Jianyu Chen Preprint, 2026 project page / code / arXiv / Hugging Face / 量子位 We introduce VPP2, a world action model with strong zero-shot generalization in video prediction and action generation, combining event-level video pretraining, single-step visual planning, and a mixture-of-transformers action module. |
|
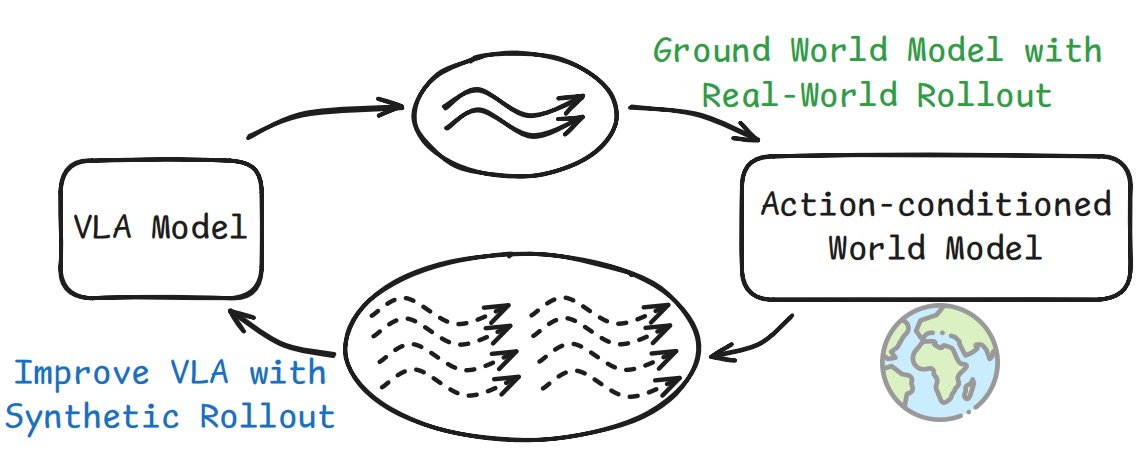
VLAW: Iterative Co-Improvement of Vision-Language-Action Policy and World Model
Yanjiang Guo*, Tony Lee*, Lucy Xiaoyang Shi*, Jianyu Chen, Percy Liang, Chelsea Finn International Conference on Machine Learning (ICML), 2026 project page / code / arxiv / twitter We iteratively improve VLA and action-conditioned world model. |
|
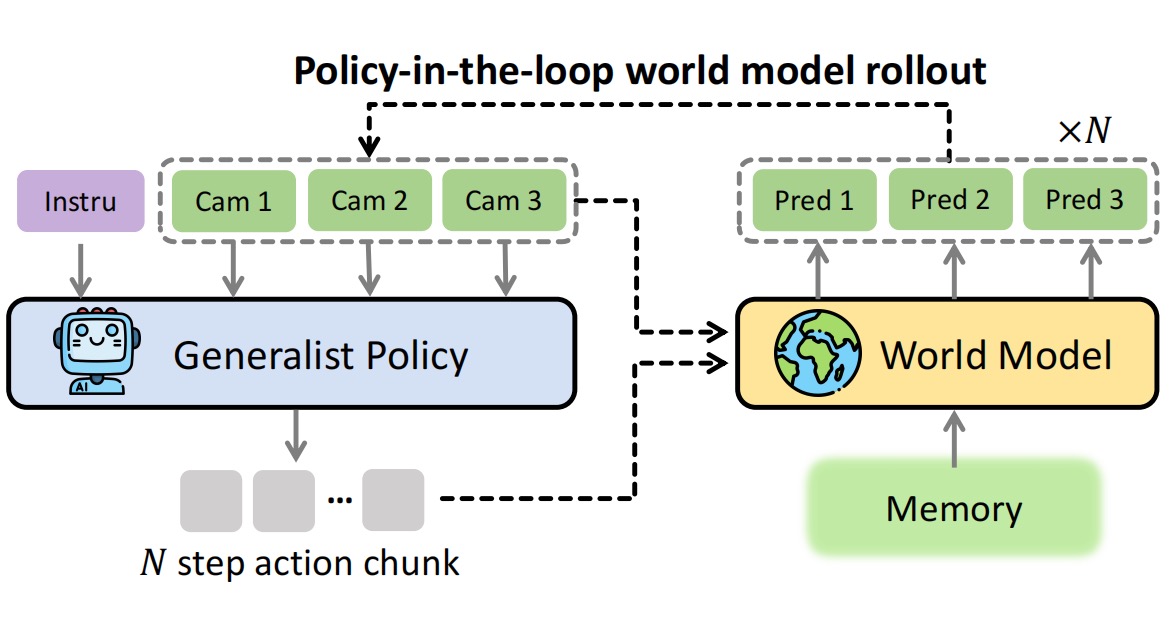
Ctrl-World: A Controllable Generative World Model for Robot Manipulation
Yanjiang Guo*, Lucy Xiaoyang Shi*, Jianyu Chen, Chelsea Finn International Conference on Learning Representations (ICLR), 2026 project page / code / arxiv / twitter We train a controllable generative world model that can be used to evaluate and improve SOTA generalist robot policy. |
|
Video Prediction Policy: A Generalist Robot Policy with Predictive Visual
Representations
Yucheng Hu*, Yanjiang Guo*, Pengchao Wang, Xiaoyu Chen, Yen-Jen Wang, Jianke Zhang, Koushil Sreenath, Chaochao Lu, Jianyu Chen International Conference on Machine Learning (ICML), 2025 (Spotlight) project page / code / arXiv / twitter / 机器之心 / 量子位 We finetune a general-purpose video diffusion model into manipulation-focused video prediction model to guide policy learning. |
|
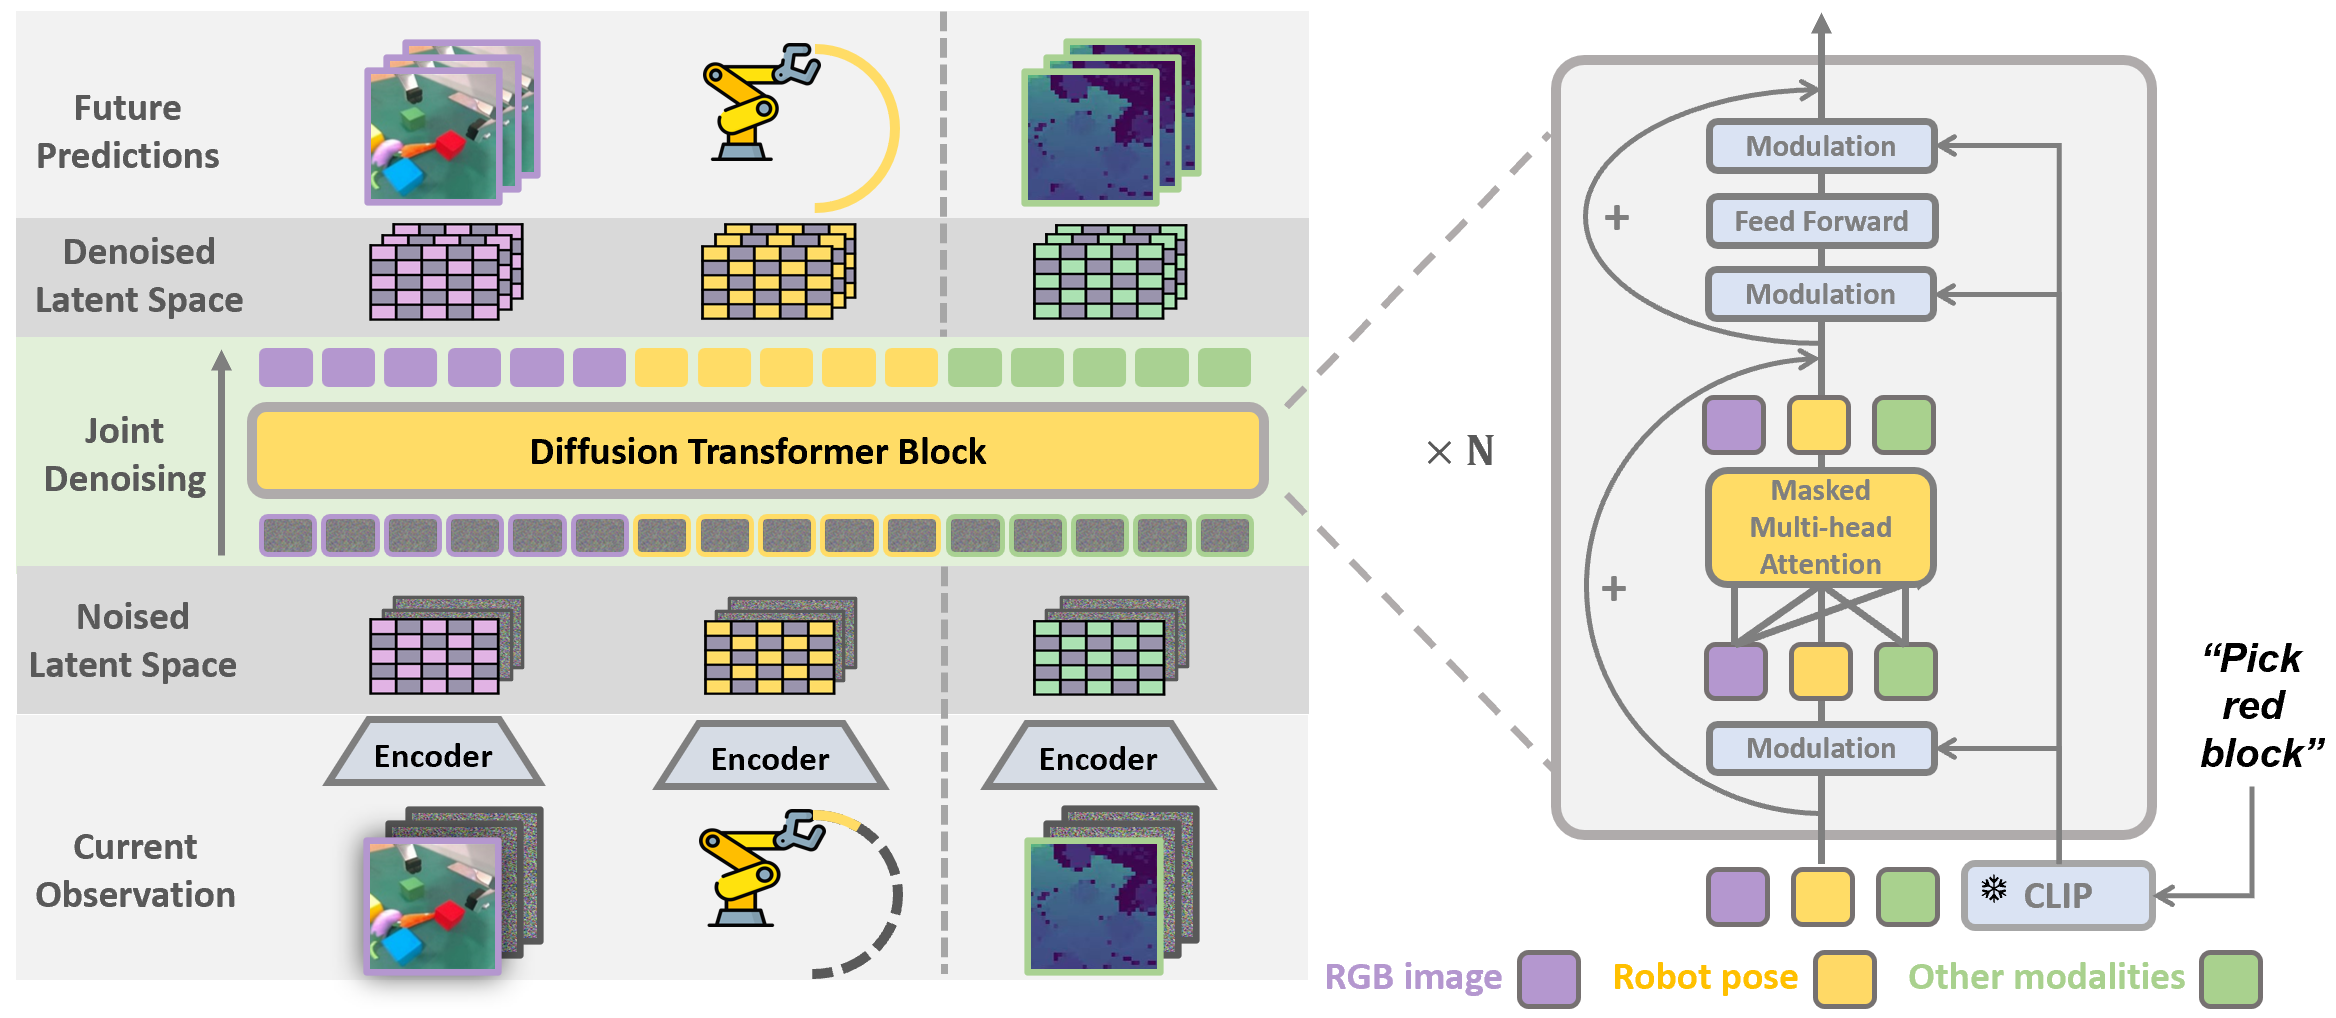
Prediction with Action: Visual Policy Learning via Joint Denoising Process
Yanjiang Guo*, Yucheng Hu*, Jianke Zhang, Yen-Jen Wang, Xiaoyu Chen, Chaochao Lu#, Jianyu Chen# Advances in Neural Information Processing Systems (NeurIPS), 2024 project page / code / arXiv We jointly predict future images and robot actions in a unified DiT network, transfering physical knowledge from internet video data to robots. |
|
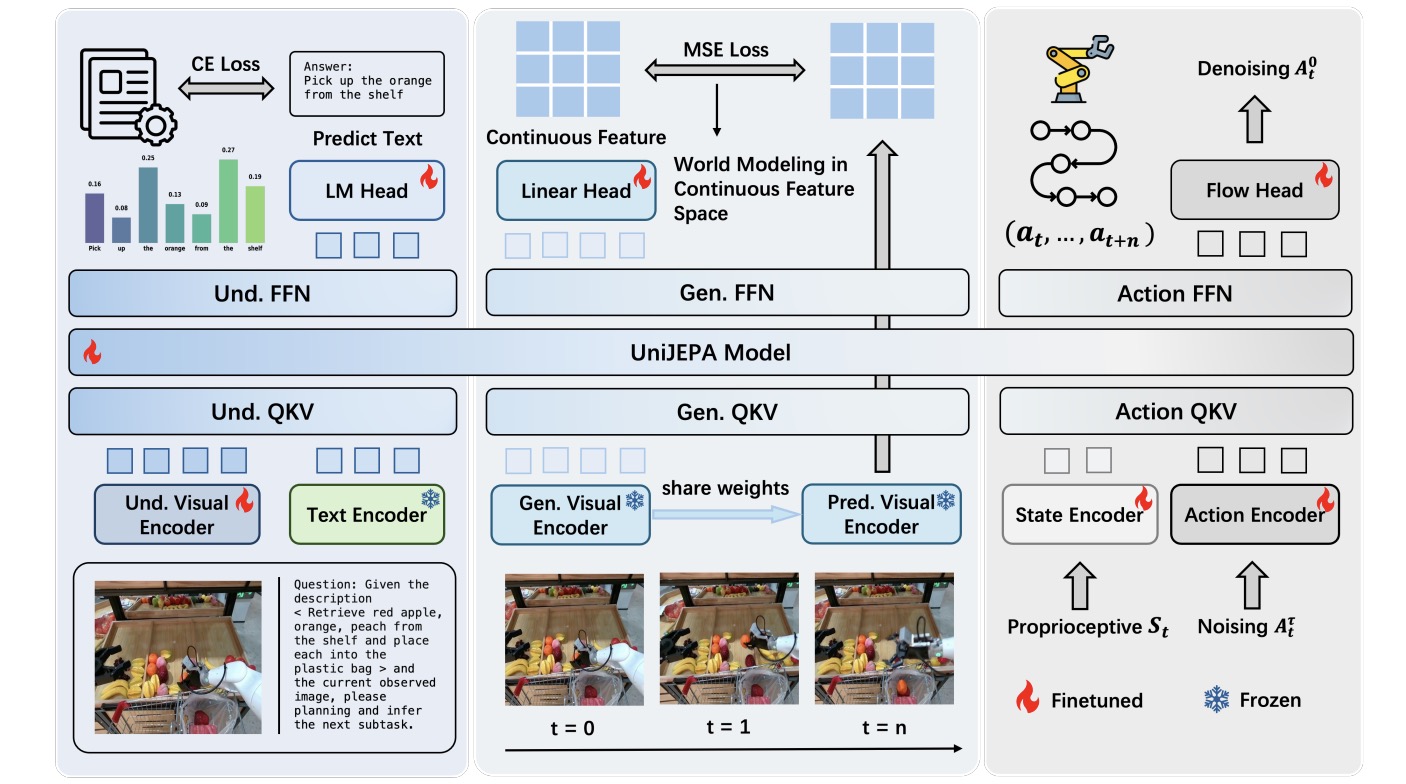
UniJEPA: Enhancing Robot Policy via Unified Continuous and Discrete
Representation Learning
Jianke Zhang*, Yucheng Hu*, Yanjiang Guo, Xiaoyu Chen, Yichen Liu, Wenna Chen, Chaochao Lu, Jianyu Chen International Conference on Machine Learning (ICML), 2026 project page / arXiv We predict latent future states to help the robot learn better policies. |
|
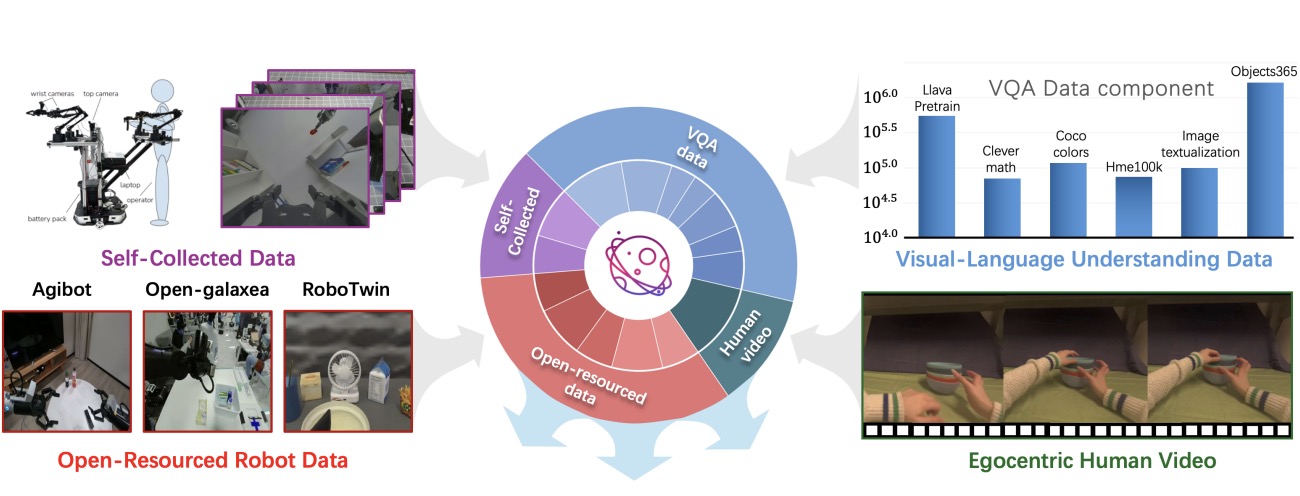
BagelVLA: Enhancing Long-Horizon Manipulation via Interleaved Vision-Language-Action Generation
Yucheng Hu*, Jianke Zhang*, Yuanfei Luo*, Yanjiang Guo, Xiaoyu Chen, Xinshu Sun, Kun Feng, Qingzhou Lu, Sheng Chen, Yangang Zhang, Wei Li, Jianyu Chen Robotics: Science and Systems (RSS), 2026 project page / arXiv We build a unified VLA model based on the Bagel model with unified understanding and generation capabilities. |
|
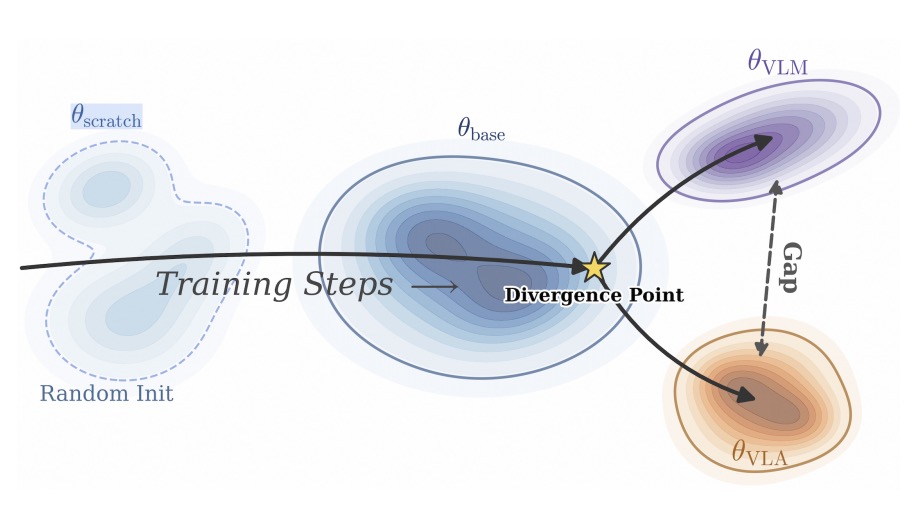
VLM4VLA: Revisiting Vision-Language-Models in Vision-Language-Action Models
Jianke Zhang, Xiaoyu Chen, Yanjiang Guo, Yucheng Hu, Jianyu Chen International Conference on Learning Representations (ICLR), 2026 project page / arXiv / code We systematically evaluate how the base VLM affect the performance of VLA. |
|
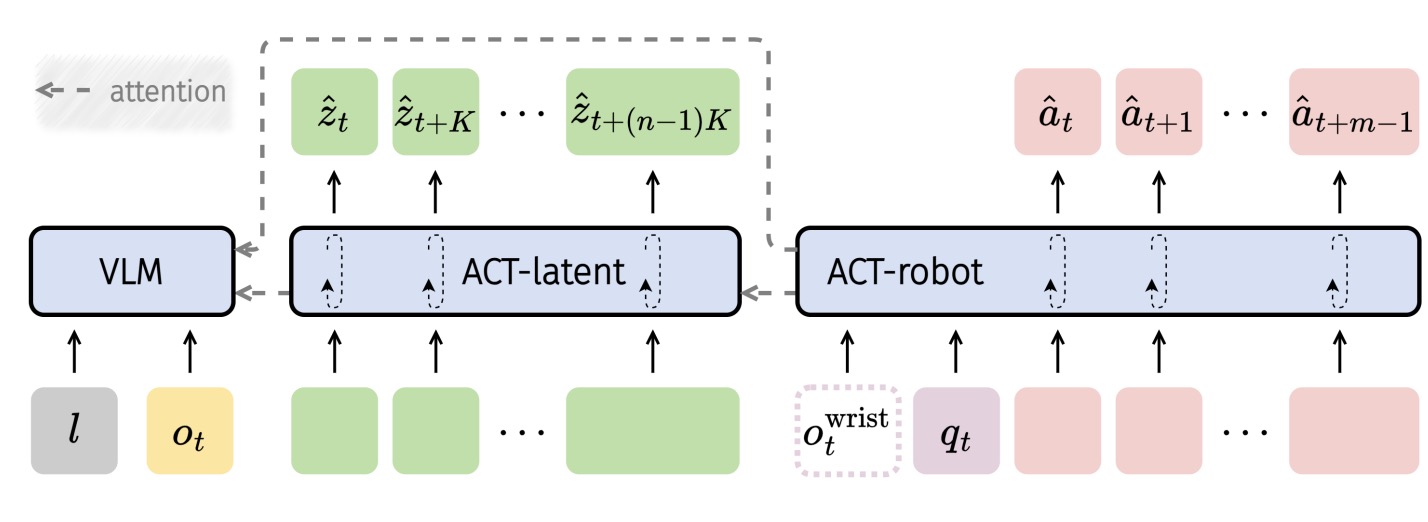
Villa-x: enhancing latent action modeling in vision-language-action models
Xiaoyu Chen*, Hangxing Wei*, Pushi Zhang*, Chuheng Zhang*, Kaixin Wang*, Yanjiang Guo, Rushuai Yang, Yucen Wang, Xinquan Xiao, Li Zhao, Jianyu Chen, Jiang Bian International Conference on Learning Representations (ICLR), 2026 project page / arXiv / code We incoperate latent action modeling into VLA model. |
|
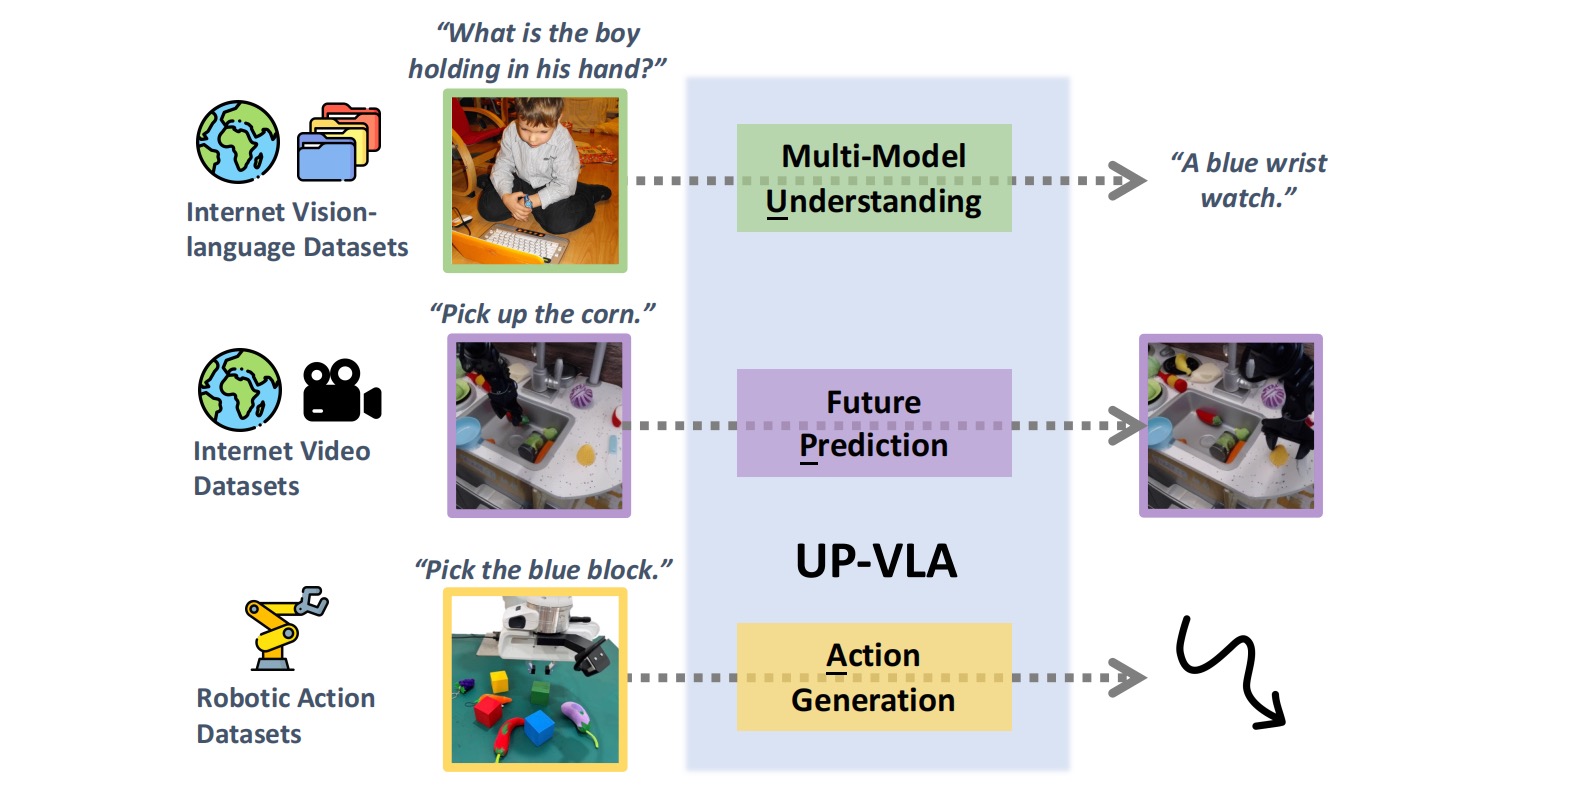
UP-VLA: A Unified Understanding and Prediction Model for Embodied Agent
Jianke Zhang*, Yanjiang Guo*, Yucheng Hu, Xiaoyu Chen, Jianyu Chen International Conference on Machine Learning (ICML), 2025 arXiv / code We incoperate both multi-modal understanding (MMU) and future prediction into VLA model, enhancing both high-level semantic knowledge and low-level visual dynamics. |
|
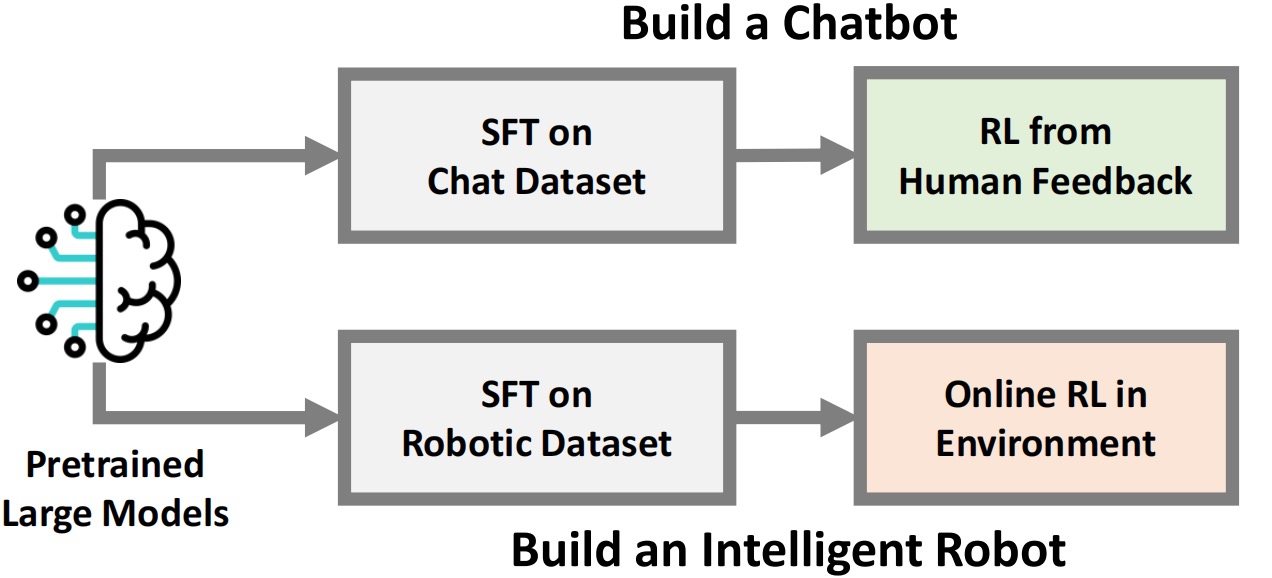
Improving Vision-Language-Action Model with Online Reinforcement Learning
Yanjiang Guo*, Jianke Zhang*, Xiaoyu Chen*, Xiang Ji, Yen-Jen Wang, Yucheng Hu, Jianyu Chen International Conference on Robotics and Automation (ICRA), 2025 arXiv / twitter1 / twitter2 We make some initial exploration on leveraging online RL to improve the VLA model! We notice that online RL for VLA can be extremely unstable and thus we adopted a iterative approach. |
|
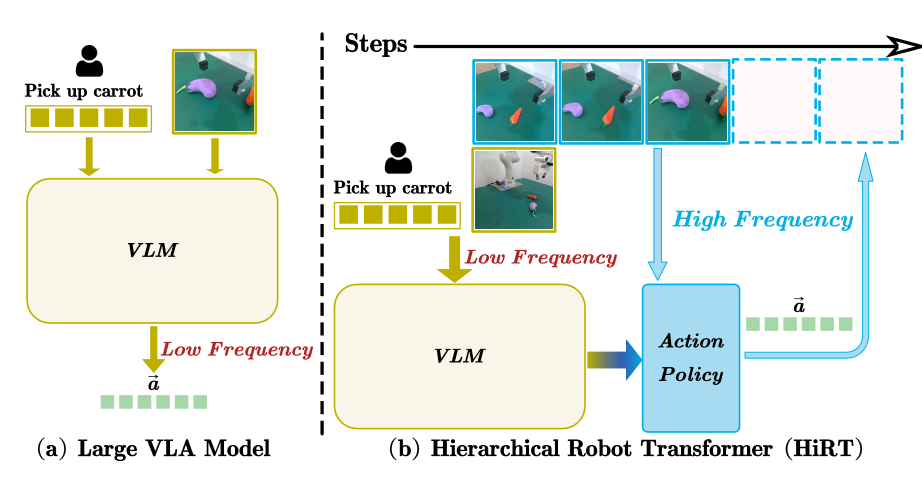
HiRT: Enhancing Robotic Control with Hierarchical Robot Transformers
Jianke Zhang*, Yanjiang Guo*, Xiaoyu Chen, Yen-Jen Wang, Yucheng Hu, Chengming Shi, Jianyu Chen Conference on Robot Learning (CoRL), 2024 arXiv / twitter / 机器之心 We finetune pretrained VLM into VLA models with hierarchical transformers, keeping the generalization ability but also much higher control frequency. |
|
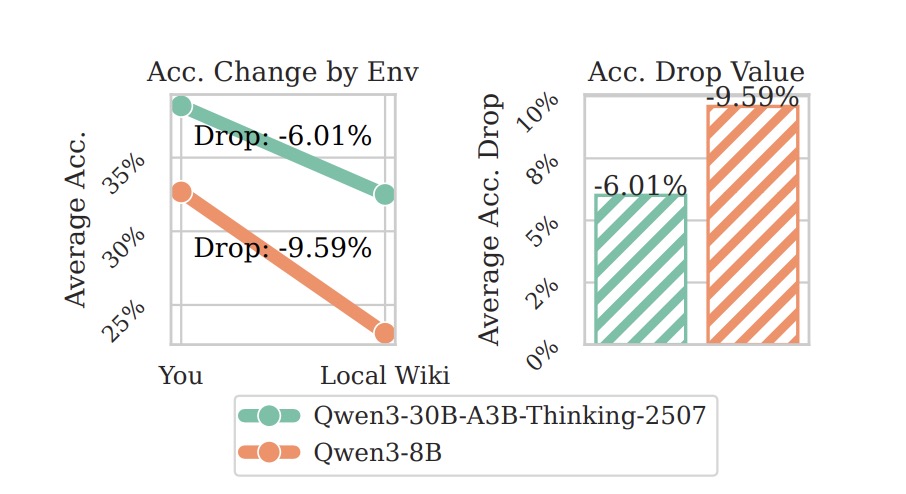
ProCeedRL: Process Critic with Exploratory Demonstration Reinforcement Learning for LLM Agentic Reasoning
Jingyue Gao, Yanjiang Guo , Xiaoshuai Chen, Jianyu Chen Annual Meeting of the Association for Computational Linguistics (ACL), 2026 arXiv Guided RL for LLM agentic reasoning. |
|
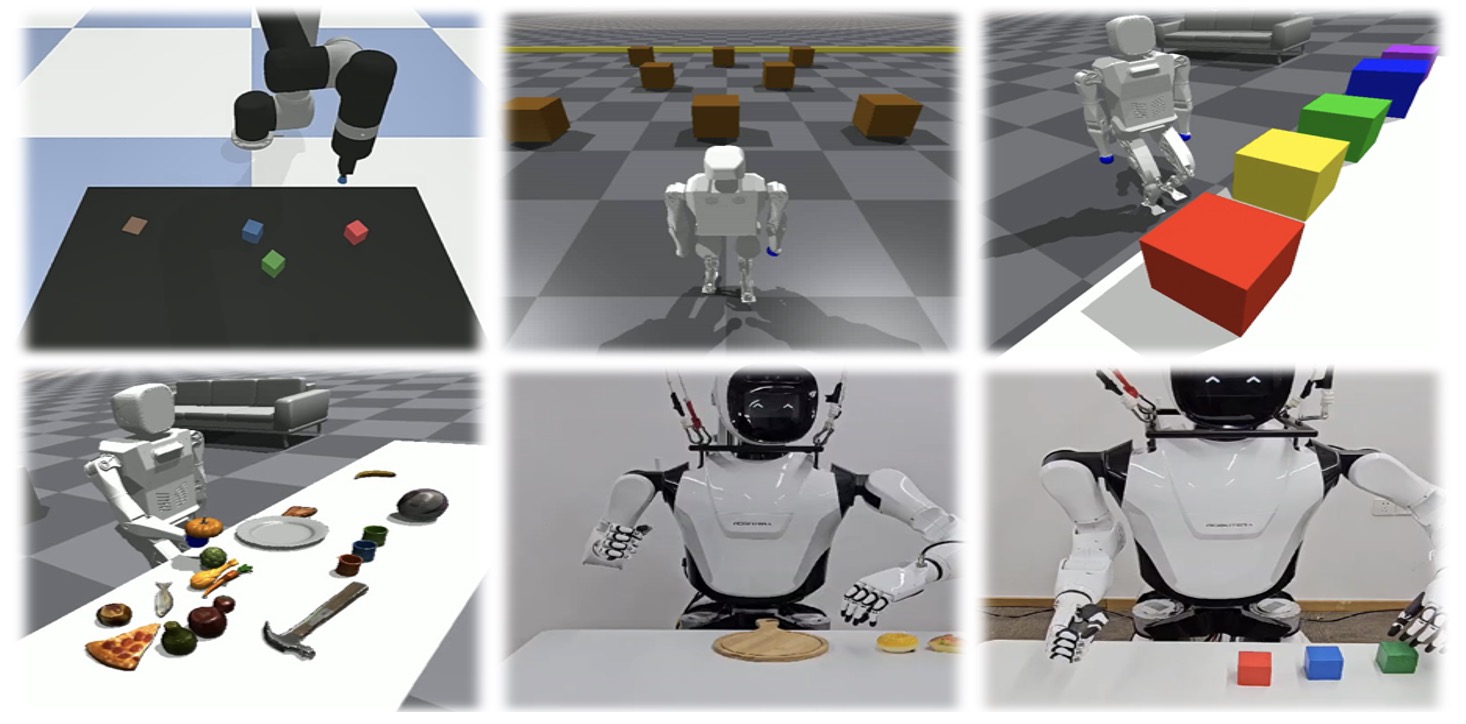
DoReMi: Grounding Language Model by Detecting and Recovering from Plan-Execution Misalignment
Yanjiang Guo* , Yen-Jen Wang*, Lihan Zha*, Jianyu Chen International Conference on Intelligent Robots and Systems (IROS), 2024 project page / arXiv We leverage LLM to pefrom both planning and monitoring, with a fine-tuned VLM as detector. |
|
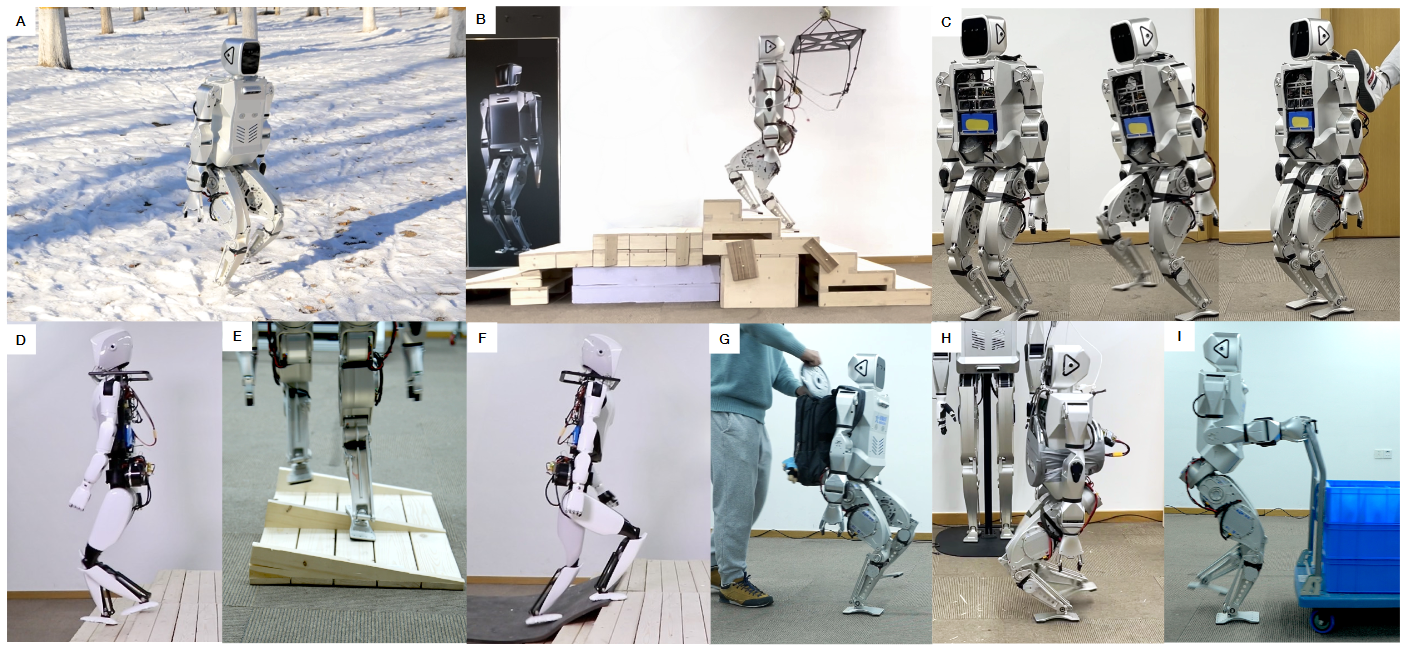
Advancing Humanoid Locomotion: Mastering Challenging Terrains with Denoising World Model Learning
Xinyang Gu*, Yen-Jen Wang*, Xiang Zhu*, Chengming Shi*, Yanjiang Guo, Yichen Liu, Jianyu Chen Robotics: Science and Systems (RSS), 2024 (Best Paper Award Finalists) project page / code / arXiv / 机器之心 We train humanoid robot to master challenging terrains such as stairs, slopes, and snow grounds with zero-shot sim2real transfer. |
|
Source code from Jon Barron. |